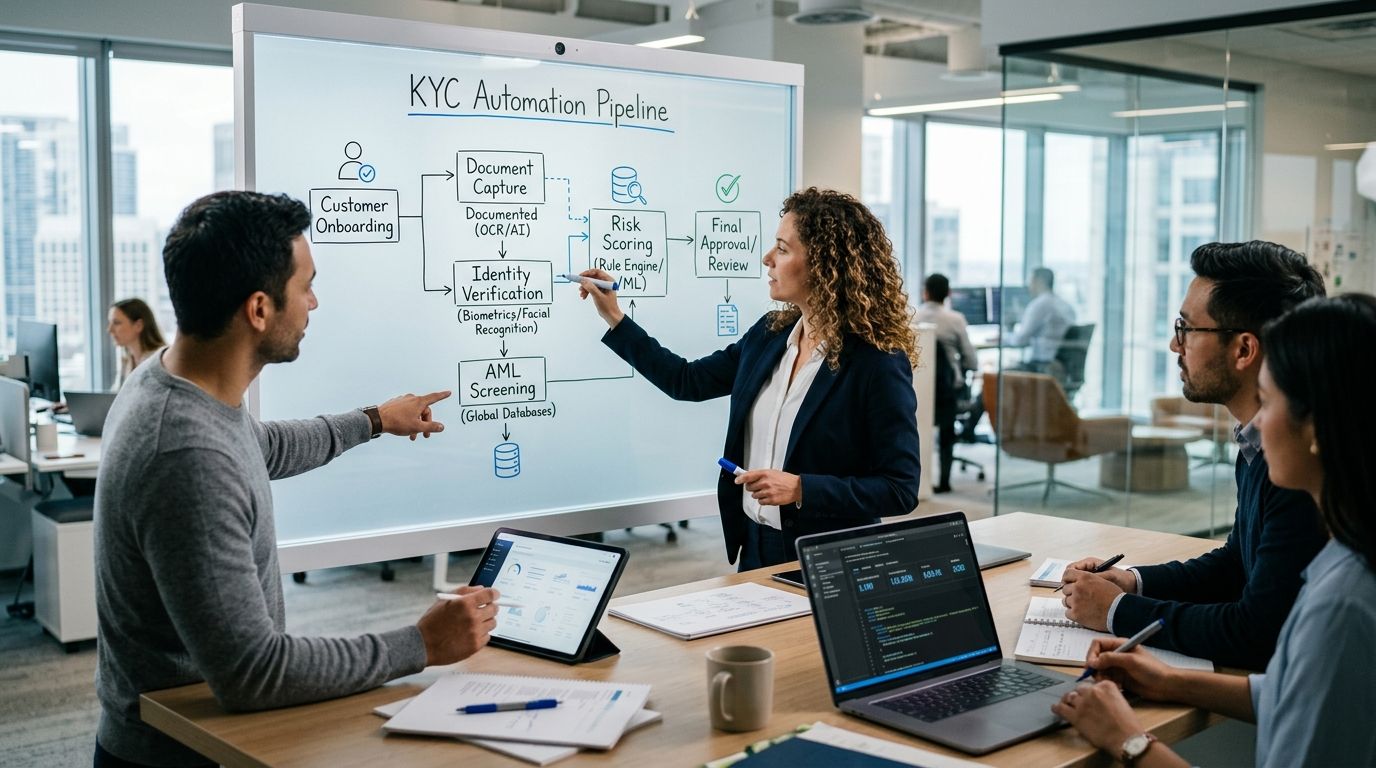
Designing a KYC automation pipeline means deciding how identity capture, document verification, sanctions screening, risk scoring, and case management connect into one system — not just picking a vendor. Get the stage order wrong or skip the human-review layer and the pipeline processes faster but fails the first regulatory audit.
- A KYC automation pipeline for banks chains five linked stages: identity capture, document verification, sanctions/PEP screening, risk scoring, and case management.
- Hybrid pipelines that pair rules-based screening with ML risk scoring cut false-positive review queues more than either approach used alone in 2026.
- KnackForge's AI agents for KYC and AML compliance in banking automate document extraction and PEP screening while routing edge cases to human reviewers.
- Continuous monitoring and periodic re-KYC, not onboarding speed, is where most 2026 pipeline failures actually originate.
- An audit trail that logs every automated decision matters as much as the automation itself under FinCEN's CDD Rule.
Why this matters
Manual KYC review still dominates onboarding at most mid-size and regional banks heading into 2026, and every added reviewer adds days to account opening and cost to compliance headcount. FinCEN's Customer Due Diligence Rule (31 CFR 1010.230) and FATF's 40 Recommendations set the floor for what any automated pipeline has to prove — not just what it has to do fast.
A pipeline that speeds up onboarding but breaks the audit trail creates more regulatory exposure than the manual process it replaced. AI agents for KYC and AML compliance in banking are built around that constraint: automate the repetitive extraction and screening work, keep a human in the loop on anything ambiguous, and log the decision either way.
How do you design a KYC automation pipeline for banks?
The pipeline runs as a sequence, and each stage feeds evidence into the next one. Skipping a stage doesn't save time — it just moves the manual work downstream to an examiner or an auditor.
- Capture identity data at onboarding — name, address, tax ID, and government ID image, pulled through a digital intake form or mobile capture rather than a scanned PDF.
- Verify documents with OCR and liveness checks — extract fields automatically and match a selfie or video capture against the ID photo.
- Screen against sanctions, PEP, and adverse media lists — run the verified identity against OFAC, UN, EU, and commercial watchlists, plus adverse media search.
- Score risk with a rules-plus-ML hybrid model — combine deterministic rules (jurisdiction, product type, transaction size) with a machine-learned score trained on historical case outcomes.
- Route exceptions to a case management queue — anything above the risk threshold, or any screening hit that isn't an automatic clear, goes to a human reviewer with the evidence attached.
- Log every decision for the audit trail — automated clears, human overrides, and the underlying data all need a timestamped record an examiner can reconstruct.
- Re-screen on a fixed schedule — periodic re-KYC and continuous monitoring catch customers whose risk profile changed after onboarding.
Rules-based vs. ML-based vs. hybrid screening
Banks generally pick one of three screening architectures. The table below lays out the honest tradeoffs of each.
| Approach | How it works | Strength | Weakness | Best for |
|---|---|---|---|---|
| Rules-based | Fixed thresholds and match logic against watchlists | Transparent, easy to explain to examiners | High false-positive rate on name variants and transliteration | Banks under a near-term regulatory deadline — Hold as a long-term architecture |
| Pure ML scoring | Model trained on historical case dispositions predicts risk | Cuts false positives significantly once tuned | Hard to explain a single decision to an auditor without added tooling | Banks with large historical case volume and a model-risk team already in place — Wait until governance is ready |
| Hybrid (rules + ML) | Rules cover known regulatory triggers, ML re-ranks and de-duplicates alerts | Balances explainability with lower review volume | More components to maintain and monitor for drift | Most mid-size and large banks building or replacing a KYC pipeline in 2026 — Buy |
The honest tradeoff: a hybrid pipeline is more work to stand up than a rules-only screen, and it needs ongoing model monitoring that a pure rules engine doesn't. It's still the configuration most banks land on because it keeps the audit trail defensible while cutting the review queue.
Data ingestion and document verification
The intake stage decides how much manual re-keying happens later. A digital onboarding form paired with OCR extraction pulls structured fields directly off a driver's license or passport instead of routing a scanned image to a data-entry queue. Liveness detection at this stage — matching a live selfie against the ID photo — closes the most common onboarding fraud path: a stolen or synthetic identity document with no matching human behind it.
Weak intake shows up two stages later as a spike in manual review, because a mis-keyed name or address throws false negatives in screening. Fixing intake accuracy is cheaper than adding reviewers downstream.
Sanctions, PEP, and adverse media screening
Screening runs the verified identity against sanctions lists (OFAC, UN, EU), politically exposed person (PEP) databases, and adverse media search. This is also where transaction-level fraud signals increasingly get folded into the same pipeline rather than run as a separate system — a customer who clears KYC at onboarding but starts moving money in a pattern that matches known fraud typologies needs the same case management queue, not a second one.
AI-powered fraud detection for banking institutions works this way: transaction monitoring and KYC screening share the same risk-scoring layer instead of running as disconnected tools that each generate their own alert backlog.
Adverse media screening is the weakest link in most 2026 pipelines. Name-matching against news sources produces enormous false-positive volume unless the matching logic accounts for entity disambiguation — matching not just the name but employer, location, and date of birth against the article context.
Case management and the audit trail
Every alert that isn't an automatic clear needs a case file: the original data, the screening hit, the risk score, and the reviewer's decision with a reason code. This is the stage banks under-invest in because it's the least glamorous — but it's the first thing an examiner asks to see.
An automated pipeline without a structured audit trail is arguably worse than a manual process, because it makes decisions faster with less visible reasoning behind each one. Building the governance layer around the automation — not bolting it on after a regulatory finding — is the difference between a pipeline that survives an exam and one that generates a consent order. AI governance frameworks for enterprises exist for exactly this problem: model documentation, decision logging, and override tracking built into the pipeline from day one.
Map your KYC pipeline gaps
Get a stage-by-stage review of where your onboarding process breaks down.
Why KYC pipeline design varies bank to bank
- Jurisdiction and license type — a bank operating under multiple regulators (state and federal, or multi-country) needs screening logic that satisfies the strictest overlapping rule set.
- Core banking system age — legacy cores without modern APIs need a middleware layer before any automation can read or write customer data.
- Watchlist vendor and data quality — the screening engine is only as good as the underlying sanctions and PEP data feed it queries.
- Customer segment mix — a bank with a large correspondent banking or high-net-worth book carries a heavier enhanced due diligence load than a retail-only bank.
- Existing case volume and reviewer headcount — the ML component of a hybrid pipeline needs historical case data to train on; banks without it start with rules-only and add ML later.
- Risk appetite set by the board — thresholds for what triggers manual review are a governance decision, not a technical one.
How long does a KYC automation rollout take for a bank?
Rollout timelines depend on core banking integration complexity and the amount of historical case data available to train the risk-scoring model, more than on the automation software itself. Banks replacing a legacy manual process typically stage the rollout by product line — starting with retail onboarding before extending to correspondent banking or trade finance, where enhanced due diligence rules are heavier.
Is rules-based or AI-based KYC screening better for banks?
Neither wins outright: rules-based screening is more explainable to an examiner, while AI-based scoring cuts the false-positive review queue once properly tuned and monitored. Most banks building a pipeline in 2026 land on a hybrid model that uses rules for known regulatory triggers and ML to re-rank and de-duplicate the resulting alerts.
FAQ
What is a KYC automation pipeline?
A KYC automation pipeline is the connected sequence of identity capture, document verification, sanctions/PEP screening, risk scoring, and case management that a bank uses to onboard and monitor customers without fully manual review. It replaces manual data entry and watchlist lookups with automated matching, while still routing ambiguous cases to a human reviewer.
How much does KYC automation reduce manual review?
The reduction depends on watchlist data quality and how well the risk-scoring model is tuned, so there's no single figure that applies across banks. Hybrid pipelines that combine rules with machine-learned scoring generally cut false-positive alert volume more than a rules-only screen, based on how the alert deduplication layer is configured.
Is rules-based or AI-based KYC screening better?
Rules-based screening is easier to explain to an examiner but produces more false positives on name variants and transliteration issues. AI-based scoring reduces the review queue once tuned, and most banks in 2026 combine both rather than choosing one.
What regulations govern a bank's KYC automation pipeline?
In the US, FinCEN's Customer Due Diligence Rule (31 CFR 1010.230) sets baseline identity verification and beneficial ownership requirements. FATF's 40 Recommendations shape sanctions and PEP screening expectations globally, and banks operating in the EU also need to account for AMLD requirements.
Do banks need a human reviewer in an automated KYC pipeline?
Yes — any alert that isn't an automatic clear needs a documented human decision with a reason code attached to the case file. A fully automated pipeline with no review layer is harder to defend in an examination than a partially automated one with clear escalation logic.
What's the biggest mistake banks make designing a KYC pipeline?
Optimizing onboarding speed while under-building the audit trail and case management layer. The pipeline that looks fastest in a demo is often the one that generates a regulatory finding a year later because decisions weren't logged.
How often should a bank re-screen existing customers?
Re-screening frequency should match customer risk tier — higher-risk customers need continuous monitoring against updated sanctions and adverse media data, while lower-risk retail customers can run on a fixed periodic re-KYC schedule. The schedule itself is a governance decision set by the bank's risk appetite, not a fixed industry number.
Can KYC automation integrate with existing fraud detection systems?
Yes, and increasingly it should — sharing a risk-scoring layer between KYC screening and transaction fraud detection catches customers who clear onboarding but later show fraud-typology transaction patterns, without running two disconnected alert systems.
One last thing
The stage banks skip most often isn't screening or scoring — it's the audit trail. A pipeline that clears customers faster but can't reconstruct why a specific case was cleared or escalated is the one that turns a routine 2026 exam into a finding. Build the logging layer before the automation, not after.


